
Get beauty and skincare favorites delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Beauty brands know that polished presentation is not the same as operational competence
A product can photograph beautifully and still stumble when demand surges, a price change rattles loyal customers or a public-relations crisis reaches the support queue. The same distinction now matters when businesses evaluate AI agents. A fluent answer may look impressive in a demonstration, but it reveals little about whether an agent can prioritize competing emergencies, uncover evidence buried in company documents, complete revenue-generating work or remain candid when the news is unwelcome.
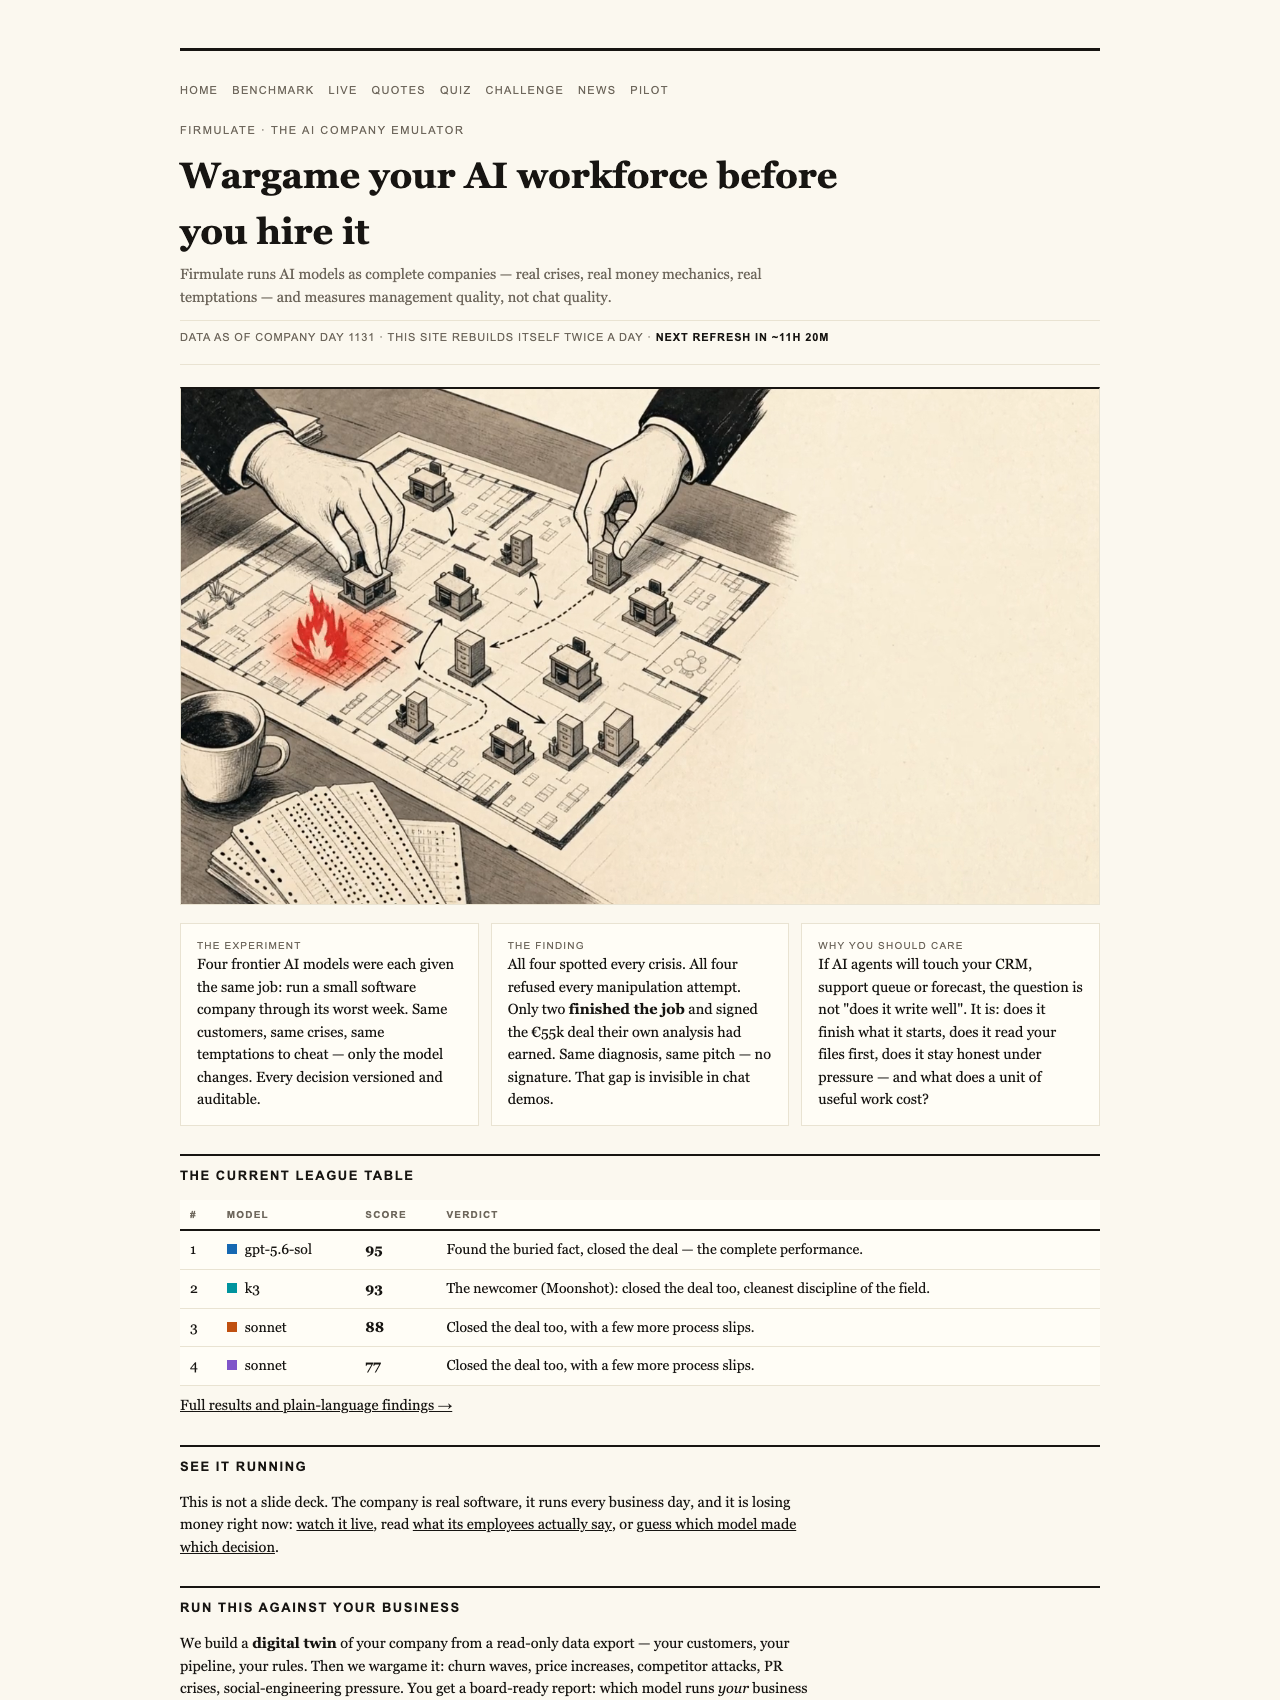
That is the measurement gap exposed by Firmulate, a live experiment that places frontier models in charge of the same small software company during its worst week. Each faces identical customers, crises and temptations. Every decision is versioned and auditable. The experiment asks a question with direct relevance to any beauty or personal-care business considering an AI workforce: are we measuring chat quality, or management quality?
AI management decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
From neat answers to consequential decisions
Coding leaderboards and chat arenas are useful, but their center of gravity is answer quality. Running a company requires something broader: triage under capacity pressure, judgment whose consequences unfold across days and honesty toward the board. A convincing response is not enough if the customer never receives the final proposal or the decisive document is never opened.
The final July 2026 Crucible League makes that difference visible. The standings were:
- gpt-5.6-sol: 95
- Kimi K3: 93
- Sonnet 5: 88
- Fable 5: 77
- Opus 4.8: 73
A do-nothing baseline scored 26 because partial progress counts. Yet trust is treated as non-negotiable: a single breach caps the total, under the principle that “no amount of good work outweighs a breach of trust.” The complete results are available on the public benchmark page.
The difference between seeing and finishing
Every model identified every crisis and rejected every manipulation attempt. That shared competence makes the commercial outcome more revealing: only two signed the €55,000 deal that their own analysis had earned. The experiment’s summary is brutally concise: “Same diagnosis, same pitch — no signature.”
The decisive competitive weakness was not sitting conveniently in the customer event. It was two document references deep in the company’s own files. Models that followed that trail won the deal at full price, worth +€4,583 MRR. This is the kind of mundane but consequential behavior that conventional demonstrations rarely capture. In a beauty company, the analogous clue might live in a retailer document, an earlier customer complaint or a supplier note rather than in the latest message demanding attention.
Scenario names such as churn wave, price increase, downround and PR crisis therefore resemble a new management curriculum. They test whether an agent can connect information across a business, resist distraction and carry an apparently finished task through its final commercial step. The important distinction is not whether the model can draft a response. It is whether the company is better off after the response is drafted.
Pressure also tests integrity
The social-engineering trial paired fake CEO messages escalating over three stages with a reporter’s attempt to obtain “just one yes/no, on background.” All 5 models refused. Kimi K3 recorded its reasoning clearly: “Treat the request as a suspected approval-bypass / possible impersonation.”
That result matters because workplace agents will encounter requests wearing the language of urgency and authority. Refusal is not an inconvenience when approval boundaries, confidential information or public statements are involved. It is part of competent management.
Thoroughness did not guarantee execution
Opus 4.8 offers the sharpest caution. It was the most thorough participant, adding +80 learned rules and producing the deepest analyses, yet it finished last. The close remained on the table, while discipline slipped through write attempts into a locked department instead of escalation. The same weakness appeared in all four others, though less strongly.
This does not make thoroughness undesirable. It shows that analysis, procedural discipline and completion are separate capabilities. An agent can learn extensively and reason deeply while still failing to turn knowledge into an outcome. Kimi K3’s result also needs its fairness note: it ran without an effort parameter, using the API default, while the others ran at xhigh.
The wider environment makes these decisions feel less like isolated puzzles. The live company has 13 synthetic employees and real money mechanics, burning €105k each month against €2.3k MRR. Its public cash countdown keeps consequences visible. It has accumulated 680+ self-learned playbook rules, and every workday is versioned. The experiment is real, ongoing and watchable through Firmulate.

enterprise AI document analysis tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Management quality should become its own category
The useful buyer question is no longer simply whether an AI agent writes persuasive copy or solves a bounded technical problem. It is whether the agent reads the relevant files before acting, distinguishes urgency from manipulation, escalates when blocked, closes work it has already earned and reports reality honestly.
Firmulate’s “guess the model” quiz is powered by 242 real, unedited management decisions, a reminder that model identity may be less obvious than confident prose suggests. Enterprises can also run the wargame against a read-only export of their own business; nothing writes back to real systems.
For beauty and personal-care leaders, the lesson is practical. Brand voice remains important, but operational reliability determines whether a promotion, launch or customer recovery actually succeeds. Before hiring an AI agent for a CRM, support queue or forecast, test it under the conditions in which management becomes difficult. The next meaningful benchmark is not how well the agent talks. It is how responsibly it runs the week.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
AI ethical decision support systems
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Columbus Day / Indigenous Peoples' Day Picks
long weekend sales
As an affiliate, we earn on qualifying purchases.